

How Website Caching Works and How to Use It Properly to Keep Your Site Stable

When a website responds slowly, the cause is not always the network connection or server configuration. In many cases, the system is processing the same requests again even though the returned content has barely changed. Caching, commonly called cache, is used to address this issue by temporarily storing generated data and serving it again for subsequent visits.
Cache can help a website reduce the number of database queries, limit the need for the server to rebuild the same page, and improve the user experience when opening content. However, it is not a switch that makes every problem disappear as soon as it is turned on. If configured without proper control, a website may display outdated data, show an incorrect login status, or cause administrators to spend time looking for the reason changes have not appeared. Therefore, it is important to understand what the cache stores, where it stores it, and when it needs to be refreshed.
What does cache actually do?
Under normal circumstances, a visit may go through several steps: the browser sends a request, the web server receives it, the application processes it, the database returns data, and the system then creates content to send back to the browser. If many people are viewing a page that rarely changes, repeating this entire process consumes unnecessary resources.
Cache creates a temporary copy of a processed result. When a similar request arrives, the system can return that copy instead of performing all the steps behind it again. This copy may be a static file, a complete HTML page, a query result, or data generated by an application component. Each type of cache has its own scope, duration, and refresh method.
Cache should be distinguished from official data storage. Data in the cache may be deleted, replaced, or expire at any time. A website should not depend on cache as the only place where original content is stored. Cache is merely an intermediary layer that helps distribute data more quickly.
Common caching layers on websites
Browser cache
A browser can store files such as images, CSS stylesheets, JavaScript code, or fonts so that it does not have to download everything again each time a user returns. This is especially useful for resources that change infrequently. When a website updates a file, using a new file name or resource version can help the browser recognize that it needs to download the new version instead of using the old one.
Browser cache is outside the website administrator’s direct control. Therefore, setting an appropriate expiration period and building a version-identification mechanism are necessary. If the expiration period is too long and the file has no way to change its version, users may continue to see the old interface. Conversely, if every resource is frequently required to reload, the benefits of caching will decrease.
Web server cache
A web server can store responses or static content to serve them more quickly. For image, CSS, and JavaScript files, the server usually only needs to read and send an existing file. For dynamic pages, the system can store the generated HTML for a certain period, depending on how frequently the content changes.
This type of cache is suitable for public pages, where many users see the same content. However, administrative pages, shopping carts, member areas, and content that depends on individual accounts often require separate rules. The same policy should not be applied to an entire website if its sections have different operational characteristics.
Object cache and database cache
Instead of storing an entire completed page, the system can store the results of frequently performed operations, such as category queries, configuration information, or shared data. When the application needs the same data, it can retrieve it from the cache layer instead of repeatedly querying the database.
Object caching is useful for websites with many dynamic operations, but it requires careful synchronization. If the original content has changed while the temporary copy has not been deleted, the application may use outdated data. Therefore, each important update operation should be accompanied by a mechanism to refresh or remove the related cache keys.
Content distribution layer cache
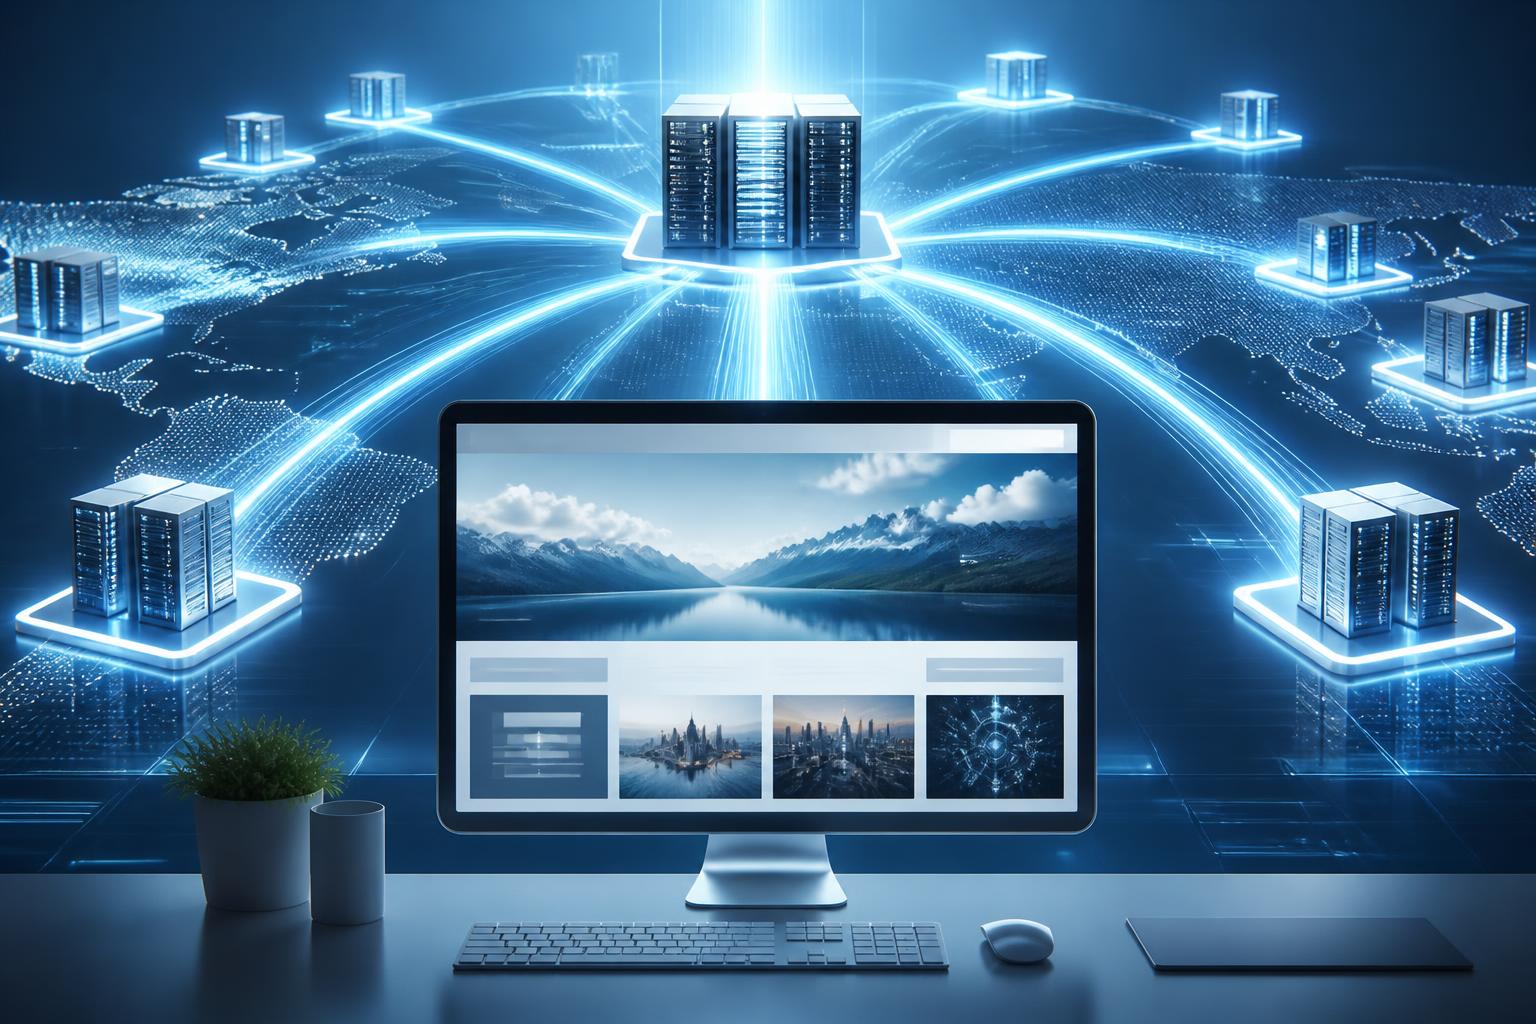
Some content distribution systems can store resources or responses at locations closer to users. The goal is to reduce the transmission distance and the number of requests that must be sent back to the origin server. This layer is especially suitable for images, static files, videos, or public content that can be distributed to many people.
Even so, adding a cache layer also means adding another place to check when the website is updated. If new content has not appeared, the cause may lie in the browser, web server, application, or distribution layer. A clear refresh procedure will help narrow down the area that needs to be checked.
Why do users still see old content?
This phenomenon often occurs after changing the interface, editing a CSS file, or updating an article. The browser may still be retaining the old file, the server may be serving a stored response, or the application may not have deleted the previous query result. If multiple cache layers coexist, clearing one layer does not necessarily change the final result.
Another cause is a storage duration that is too long compared with the frequency of content updates. Pages that rarely change may benefit from longer expiration periods, while news pages, product prices, or service statuses require shorter and more flexible policies. This does not mean that all dynamic pages must disable caching. Instead, it is necessary to determine which parts change frequently and which can be stored safely.
During the process, do not rush to clear the entire cache after every edit. Doing so may force the server to regenerate large amounts of content at the same time and reduce operational efficiency. It is better to identify the exact resources or groups of affected pages and then refresh them selectively. After clearing the cache, the result should be checked using a new session and on multiple types of devices if the change involves the interface.
Principles for configuring cache safely
First, classify content according to how often it changes and how private it is. Shared static resources are generally easier to cache than content associated with personal accounts. Pages containing users’ private data should be excluded or handled with an appropriate policy to avoid the risk of displaying information from one session in another.
Next, there should be a way to identify versions of static resources. When a file is edited, its name or version indicator should change so that the system knows it is a new resource. This reduces dependence on forcing all users to clear their caches manually.
Third, cache refreshing must be incorporated into the publishing process. The person responsible for updating content needs to know which changes automatically refresh the cache, which require additional action, and how to confirm the result. The clearer the process, the lower the likelihood of errors occurring after content is published.
Finally, cache should be monitored rather than configured once and then forgotten. It is possible to track response times, cache hit rates, errors occurring after refreshes, and pages that are frequently served with outdated data. These signals help administrators adjust policies based on actual conditions instead of applying one rigid setting to every section.
How does cache affect user experience and SEO?
Cache is not the only factor determining search rankings, but a website’s response speed and usability affect the user experience. A page that loads consistently makes it easier for readers to access content, especially when they are using limited devices or connections. When cache is configured correctly, the server also has more capacity to handle requests that cannot be cached, such as login actions or data updates.
However, speed should not be achieved at the expense of accuracy. A fast page that displays an outdated article, an incorrect price, or a false service status still creates a poor experience. A website needs to prioritize accurate content and then find ways to temporarily store the parts that can be cached safely. This is why classifying data is more important than simply enabling as many cache layers as possible.
Checking procedure when a website shows unusual behavior
When content is found not to have updated, first determine whether the issue appears for all users or only on one device. Next, check when the change was made, the scope of the affected content, and which cache layers are being used. Recording the steps that have been taken will help prevent the cache from being cleared repeatedly without knowing which change produced the result.
After refreshing the suspected layer, reopen the page in a new session and check related pages as well. If the issue remains, examine the layers behind it instead of continuing to repeat the same action. For major changes, check the home page, several content pages, the login area, and form-submission functions to ensure that the refresh has not caused unintended effects.
Cache is an important tool for helping a website operate quickly and conserve resources, but its effectiveness depends on how the policy is designed. By understanding each cache layer, distinguishing public content from private data, building a versioning mechanism, and establishing a specific refresh procedure, administrators can take advantage of speed while still protecting accuracy. A good caching system is not the one that stores the most, but the one that knows what content should be stored, how long it should be stored, and when it needs to be refreshed.