

Proactive Website Monitoring: How to Detect Problems Before Customers Report Them

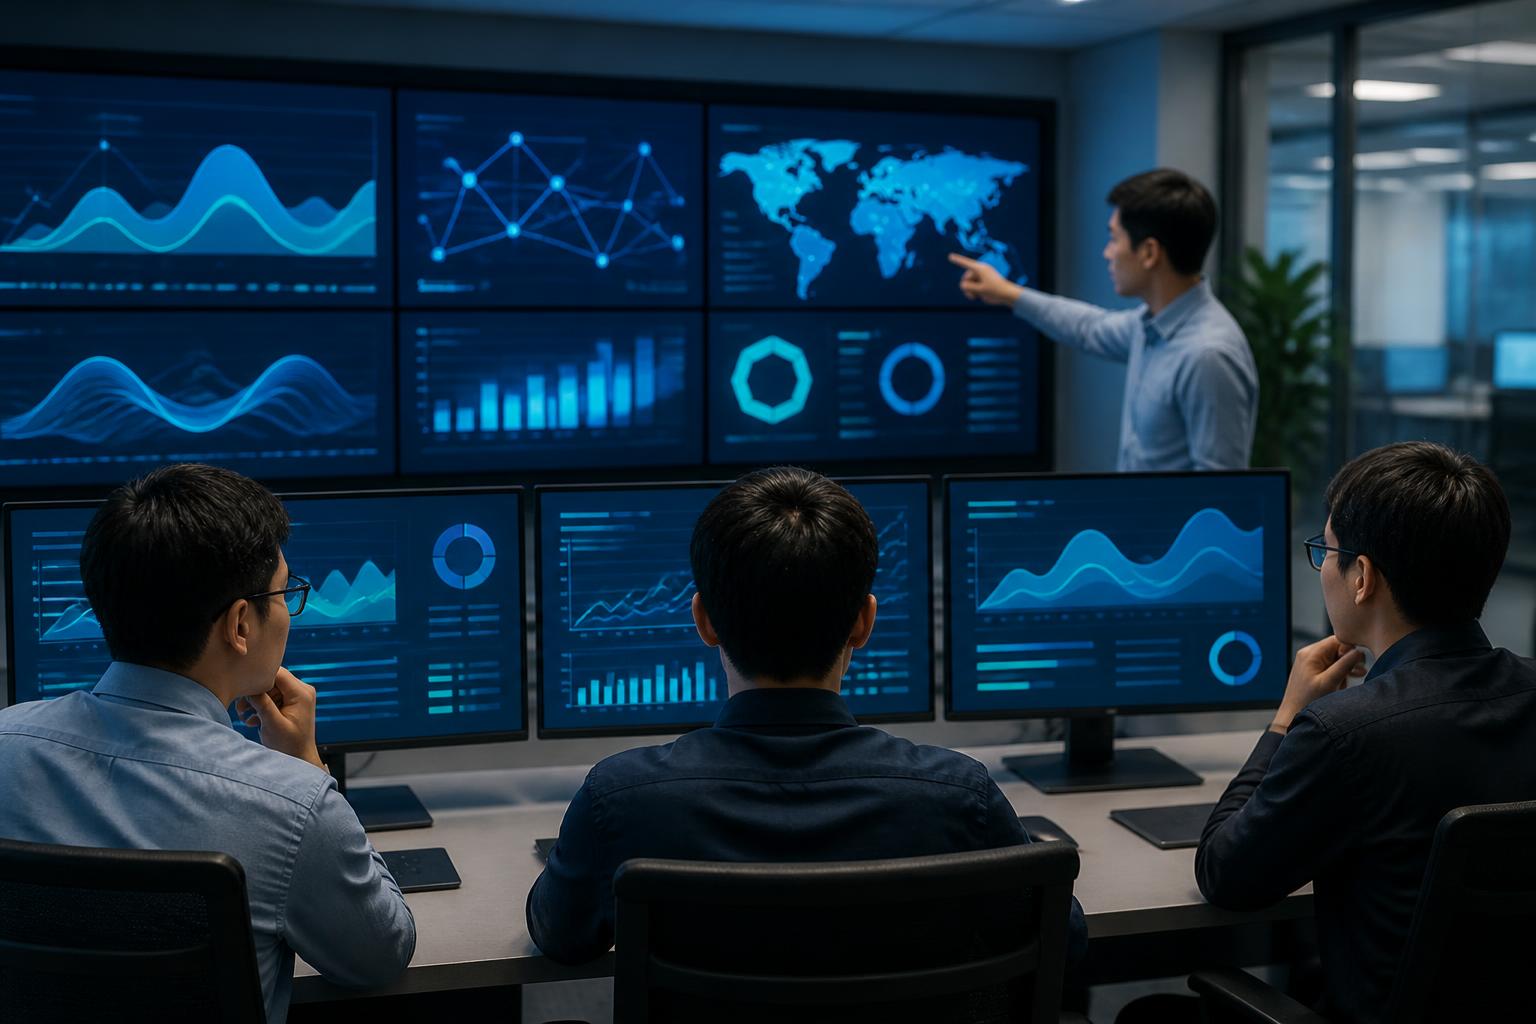
A website may still be working on an administrator’s computer but be inaccessible from another region, load very slowly on mobile devices, or repeatedly return errors at certain times. If they only wait for customers to report problems, businesses often learn about an incident after the user experience has already been affected. Therefore, proactive website monitoring is an important part of operations, especially for online stores, information portals, service websites, and systems with login functionality.
Website monitoring does not mean continuously opening the homepage in a browser. It is the automated and systematic process of checking many different components, from connectivity and response time to error codes, forms, security certificates, and server resources. The goal is not only to know whether a website is working or down, but also to understand where a problem occurs, how long it lasts, and which groups of users it may affect.
Why is manual checking often not enough?
Manual checking is valuable during acceptance testing or when handling a specific situation, but it is not suitable for continuous monitoring. An administrator cannot access a website at every moment, from every network connection, and on every device. A brief error lasting a few minutes may go unnoticed if it occurs outside working hours. Meanwhile, customers visiting at that time may still encounter a blank page, a server error, or an incomplete payment process.
In addition to timing issues, checking through a personal browser can produce results that differ from those experienced by external users. Cached data, an internal network connection, a logged-in session, or device configuration may cause a page to display normally even though the system is experiencing problems for other users. Some issues also appear only on a specific URL, such as the contact page, search page, account area, or form-submission step.
Automated monitoring provides a more independent perspective. A monitoring system can send requests at regular intervals, record the results, detect unusual changes, and send alerts to the responsible person. This gives the technical team an opportunity to respond before an incident spreads or before the customer service department has to handle numerous similar complaints.
The layers that need to be monitored on a website
Accessibility and response codes
The most basic layer is checking whether the website can receive and respond to requests. Monitoring tools typically access one or more selected addresses, then check the response code, waiting time, and response content. This helps identify situations such as a server not responding, a URL being redirected unusually, or a page returning an error in the server-related category.
However, simply receiving a response is not enough. A website may return an error page even though the connection has been established successfully. Therefore, the checking rules should clearly define which result is considered normal. For important pages, the system can check whether a distinctive piece of content appears instead of merely checking whether the page responds.
Response time and loading speed
A website that is not completely down can still provide a poor experience if it responds slowly. An increase in response time may be related to an overloaded server, lengthy database queries, problems with third-party resources, or an inefficient application-side processing workflow. Monitoring response-time trends helps detect degradation before the website becomes inaccessible.
It is important to distinguish between the time it takes for the server to begin responding and the time it takes for users to see and interact with the content. These two metrics reflect different stages. A server may respond quickly while the page still loads slowly because of large images, numerous scripts, or resources from external services. Therefore, monitoring should be combined with performance checks on pages that play an important role.
Business functions
The fact that the homepage opens does not mean the entire website is working properly. An online store may still display products while its add-to-cart function is failing. A service website may load well while its contact form cannot be submitted. A membership system may allow users to open the login page but reject every authentication request.
These functions need to be checked using suitable scenarios and at a cautious frequency so they do not create unnecessary load or generate false data. Scenarios can focus on non-mutating steps, such as opening a page, searching for sample content, or checking for the presence of an interface element. If data submission needs to be tested, there must be a mechanism to distinguish monitoring requests from real transactions and prevent interference with business data.
Certificates and secure connections
Secure connections need to be monitored as part of website operations. Expired certificates, unsuitable configurations, or resources loaded over an insecure connection can cause browsers to warn users. Early warnings about certificate expiration give the team time to renew the certificate and recheck the entire process before an interruption occurs.
Checks should also include important URLs rather than testing only the homepage. Some pages may generate separate warnings because of the way resources, redirects, or subdomains are configured. Regular monitoring helps detect these differences under conditions that are close to real-world access.
Good alerts should support action, not just create more notifications
A monitoring system can send a large number of alerts and still be ineffective if recipients do not know what to do next. An alert should clearly state which website is experiencing a problem, which type of check failed, when it began, how many consecutive checks have failed, and the current status. This information helps the on-call person distinguish a temporary error from an incident requiring immediate intervention.
Emergency alerts should not be sent for every minor change. If response time increases slightly during one check but quickly returns to normal, repeated alarms may cause the person responsible to overlook important notifications. Different thresholds, confirmation periods, and priority levels can be applied to different types of incidents. An error that makes a core function unusable needs to be handled differently from a slight indication of increased latency.
The alert-receiving channel should also match the way operations are organized. An incident outside working hours may need to be sent to the technical on-call person, while an issue involving content or forms may be routed to the website team. Whether email, a task-management system, or an internal communication channel is used, the process must clearly identify who receives the alert and who has the authority to decide the next step.
From alerts to finding the cause
Monitoring delivers value only when its results are combined with logs and other operational information. When a check fails, the administrator should compare that time with server logs, application logs, resource usage, and recently deployed changes. If the error began immediately after an update, the investigation can focus on the new version or configuration. If the error occurs periodically, scheduled tasks, resource limits, or traffic that increases at certain times should be considered.
Recording incident history is also essential. A simple tracking table can include the start time, recovery time, scope of impact, suspected cause, confirmed cause, and preventive measures. This data helps the team identify recurring patterns instead of treating each occurrence as an isolated event.
Not every error originates from the server. The problem may lie with a network provider, a third-party service, domain-name configuration, the database, the source code, or the deployment process. Therefore, monitoring results should be viewed as signals that guide the investigation, not as the sole evidence for determining the cause.
Building a monitoring process suited to the website’s scale
A small website can start with a few essential checks: the homepage, important URLs, response time, and certificate expiration. As the system grows, checks can be added for the login area, forms, search, content servers, or functions that generate revenue. Expanding gradually helps avoid complex configurations that do not provide additional value.
Each check needs an owner and a clear response procedure. If no one reviews the alerts or has access to resolve the problem, adding more monitoring points only increases the sense of false security. Periodically reviewing the checklist is also important because URLs, business processes, and responsible personnel may change over time.
In addition to external monitoring, businesses should observe internal metrics such as processor usage, memory, storage capacity, the number of connections, and the status of background services. These two perspectives complement each other. External checks show what users are experiencing, while internal data helps explain how the system is being affected.
Monitoring does not replace a contingency plan
Early alerts help shorten detection time, but they do not automatically restore a website or prevent every incident. Businesses still need appropriate backups, recovery procedures, an emergency contact list, and a communication plan for when an important service is unavailable. These plans should be tested under real-world conditions rather than merely stored in documentation.
The team also needs to agree on the criteria for when to pause a change, when to roll back a version, and when to notify customers. A clear process helps reduce rushed decision-making under pressure. After every significant incident, the team should conduct a root-cause review and update the process rather than simply restoring the website and overlooking the lessons learned.
Conclusion
A stable website is not merely one that still opens when an administrator checks it. It is a system monitored from multiple perspectives, capable of detecting signs of degradation, alerting the right people, and supporting the search for the cause within a reasonable time. By combining checks of accessibility, performance, business functions, secure connections, and server data, businesses can move from reactive problem-solving to more proactive operations.
The starting point does not have to be complicated. Identify the most important pages and functions, establish normal criteria, set up contextual alerts, and record how each incident is handled. Over time, monitoring data will become a foundation for improving infrastructure, deployment processes, and the quality of service provided to users.


