Website Performance Monitoring Software: Turning Operational Data into Improvement Decisions

A website may still open on the technical team’s computers while responding slowly to users in one region, failing to load completely on mobile devices, or generating an error at a critical step in the ordering process. Problems like these often do not appear as a completely obvious incident. They may begin with a slight increase in response time, a JavaScript file that fails to load, a lengthy database query, or an unstable response from a third-party service.
That is why website performance monitoring software is playing an increasingly important role in digital operations. This tool is not only used to check whether a website remains accessible, but also to collect data on speed, availability, application errors, and actual user experience. When deployed properly, a monitoring system creates a continuous picture of the website, helping teams detect abnormal trends before they become complaints or disrupt business operations.
How Is Website Performance Monitoring Different from Manually Checking a Website?
Manual checking usually takes place when someone actively opens a website, tries a few actions, and then gives an assessment. This approach is useful when checking an interface or verifying a specific error, but it cannot cover the website’s operation throughout the entire day. Users access websites from different networks, devices, browsers, and locations. A page may work normally in the morning but become slower during peak hours, or encounter an error only when an integrated service temporarily fails to respond.
Monitoring software collects data on a schedule or continuously, depending on the type of system. It can send requests to important pages to measure response times, check status codes, and confirm that basic content is still being served. For websites with more complex processes, the tool can simulate a sequence of actions such as opening a page, searching, logging in, adding a product to a cart, or proceeding to checkout. The goal is not to completely replace in-depth testing, but to create a constant layer of observation for the operating environment.
Data Layers That Need to Be Monitored
Availability and Response Time
This is the foundational monitoring layer. The system needs to show whether the website is accessible, how long it takes to respond, and how broadly an incident occurs. Checking from multiple access points can help distinguish a localized error from an issue related to the server, network, or content distribution configuration. However, a page returning a successful response does not necessarily provide a good experience. If the wait is too long or important resources fail to load, users may still leave before completing an action.
Page-Load Performance
Page-load performance involves many components: domain name resolution time, connection setup, server response, resource size, how the browser processes code, and the order in which content is displayed. Monitoring software can provide data for each stage so that teams do not have to guess the cause based on a single aggregate figure.
In practice, improving performance does not necessarily begin with a major change. An overly large image, a library that is no longer needed, an unoptimized query, or an unsuitable cache configuration can all affect load time. Detailed data helps technical teams identify which problems have a significant impact instead of optimizing indiscriminately.
Browser and Application Errors
Many errors occur only on the browser side. A piece of code may conflict after an update, a form may fail to submit data, or a functional button may stop working under a particular condition. If the team monitors only the server, it may miss these signs because the server is still returning the page normally.
User experience monitoring solutions commonly record JavaScript errors, information about the page where an error occurred, and relevant technical context. Data should be collected selectively, avoiding the storage of unnecessary sensitive information. When analyzing errors, businesses should focus on the level of impact, frequency of occurrence, and the journey that users are unable to complete, rather than simply counting the total number of errors.
Actual User Experience Metrics
Simulated testing shows how a predefined process operates. In contrast, data from actual users reflects the diversity of devices, networks, and access contexts. These two types of data complement each other. Simulated testing can detect an incident before users encounter it, while real-user data shows the conditions under which a problem is occurring.
For websites that depend on organic search or online conversions, operations teams can combine performance data with information about landing pages, devices, and access journeys. This approach helps prevent them from looking only at average speed while overlooking user groups that are having a poorer experience.
Alerts Have Value Only When They Are Linked to Action
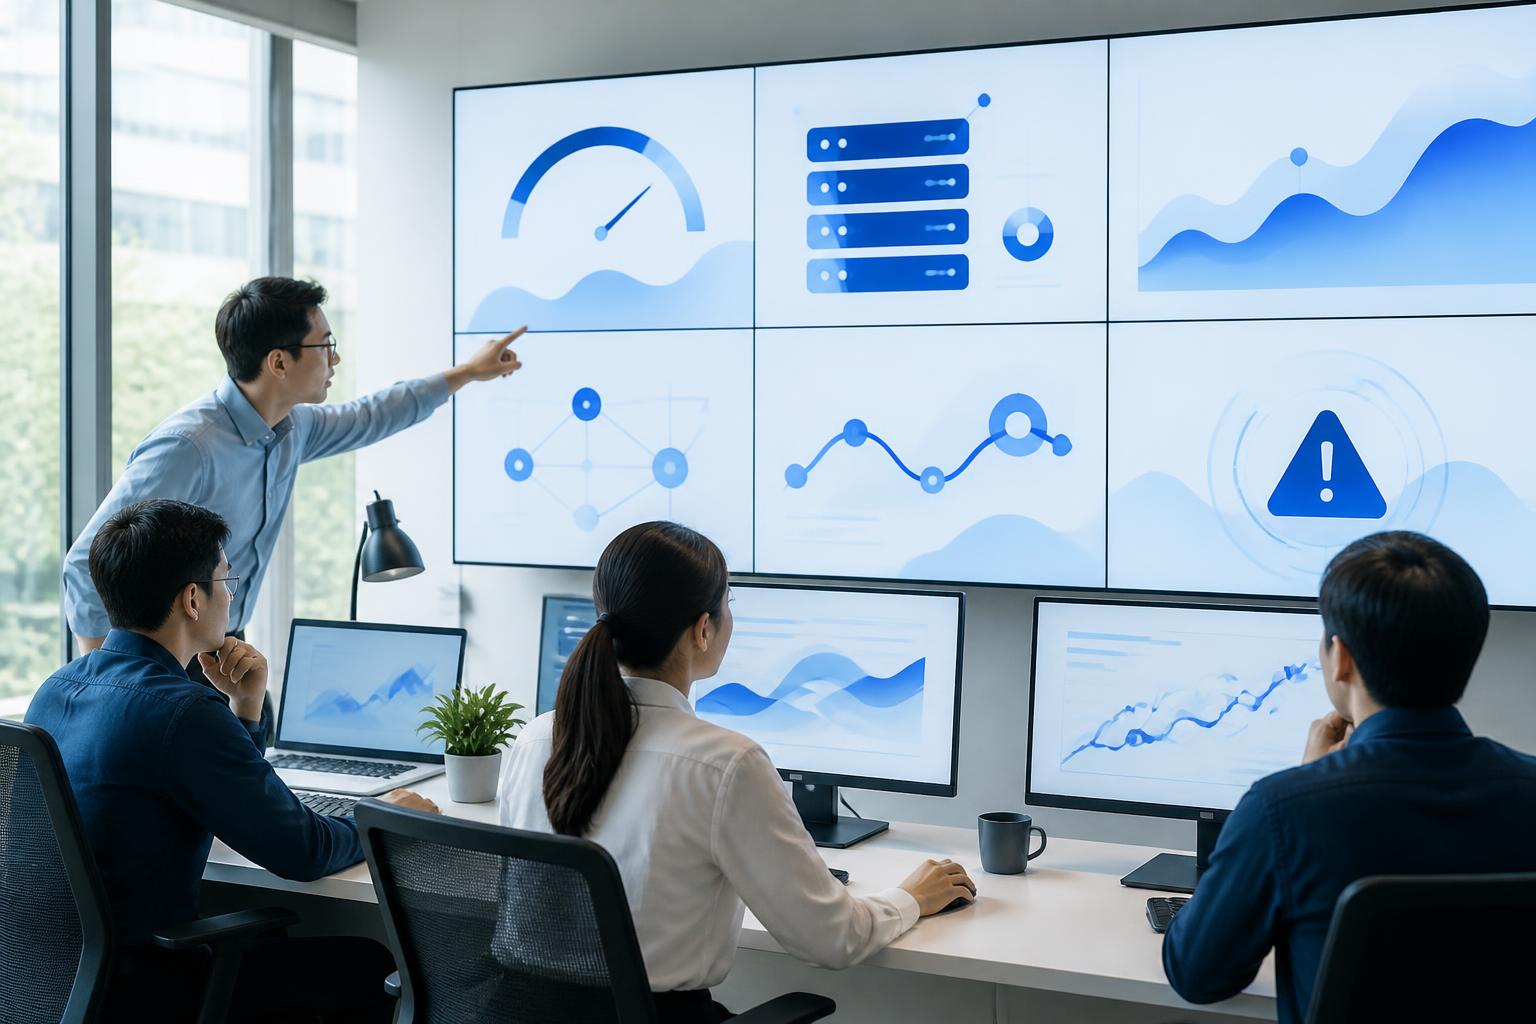
A monitoring system can generate a great many alerts, but a large volume does not mean better operational capability. If alert thresholds are set too low, teams will constantly receive notifications about insignificant fluctuations. If they are set too high, serious incidents may be detected too late. Therefore, each alert should be linked to a specific question: Which metric has changed, what does the extent of the change mean, who needs to respond, and what is the first verification step?
Alerts should also be prioritized by level. A homepage that responds slowly for a short period may require monitoring, while a login or payment process that does not work should receive higher priority. The notification channel should also match the level of urgency. Not every issue needs to be sent to the entire team through every channel, because doing so can easily create alert fatigue.
More importantly, alerts need context. A notification that merely says the website is slow will make it difficult for the person handling the issue to begin work. More useful information might include the start time, the affected region or check point, which step in the process failed, a comparison with the recent baseline, and changes that were just deployed. This data shortens the incident-triage process and reduces the need to start checking again from scratch.
Baselines and Reading Data by Trend
There is no single speed threshold that suits every website. A news site, online store, and administrative portal have different resource structures, so each should be evaluated based on its own characteristics. Businesses can establish a baseline by observing normal activity during different periods, then identifying the usual range of fluctuation and the changes that require investigation.
Reading data by trend is often more valuable than looking at a single check. If response time gradually increases after each feature is added, this may signal a need to review the architecture or release process. If errors are concentrated on one type of device, the development team can inspect the interface and code running in the corresponding environment. If metrics worsen by time of day, traffic, server resources, and background tasks should be considered.
These comparisons do not automatically prove the cause. They provide a basis for forming hypotheses and conducting further checks. A good analysis process always distinguishes between observed data and conclusions that need to be verified, avoiding the rush to blame the server, source code, or an external service when there is not yet enough information.
Criteria for Choosing Monitoring Software
Before choosing a tool, businesses should identify the website’s most important journeys. If the primary goal is to know when the website goes down, an availability-checking solution may meet the basic need. If the business needs to monitor login, search, or purchasing processes, the tool must support multistep transaction checks. For development teams, the ability to trace errors and link data with a work-management system may be more important than an attractive dashboard.
The scope of measurement also needs to be considered. The tool should allow monitoring of locations or environments that are appropriate for the target user group, while providing enough detail for analysis without increasing the administrative burden. The ability to integrate with notification channels, manage role-based access, retain data history, and export reports also directly affects long-term use.
Cost is not limited to the service plan. Businesses also need to account for the time required to configure the system, maintain test scripts, handle alerts, and train users. A solution with many features but no clearly assigned owner will have difficulty creating value. Conversely, a tool that is sufficient for the need and integrated into release and incident-response processes may deliver more consistent results.
Implement in Stages to Avoid Overload
The initial phase should focus on a number of pages and journeys that directly affect the website’s operations. A business can begin with availability checks, then add response-time measurement, action simulation, and browser-side error collection. Each type of check needs an owner, evaluation thresholds, and a response method for when an anomaly is detected.
Once the system has accumulated sufficiently stable data, the team should review recurring alerts, remove notifications that do not lead to action, and update scripts when the website changes. New feature releases should also include a review of paths, interface selectors, and authentication conditions to prevent an outdated script from producing incorrect results.
Businesses also need to pay attention to privacy and security during the monitoring process. Session data, form content, account information, or transaction data should not be collected beyond what is necessary. Test scripts should use appropriate test accounts, while access to the monitoring dashboard must be restricted according to role.
The Greatest Value Lies in the Coordination Process
Monitoring software cannot fix every problem on its own. Its value is realized only when data is connected to a clear coordination process among development, operations, security, content, and the teams responsible for business functions. When an incident occurs, the team needs to know who will verify it, who will decide whether to pause a release, who will communicate with customers, and when a follow-up assessment should take place after remediation.
After each incident, monitoring data can support a review of the cause, detection time, resolution time, and signals that appeared beforehand. The purpose is not to find someone to blame, but to improve the system and processes so that similar errors can be recognized more easily. Over time, a business can build an operational knowledge base based on real cases rather than relying solely on assumptions.
In an environment where websites are constantly changing, performance monitoring should be viewed as a regular activity rather than a task performed only after an incident. A suitable platform will help businesses see the relationship between speed, stability, user experience, and business goals. When metrics are interpreted in the right context and linked to specific actions, monitoring software becomes a decision-support tool, helping websites improve in a more evidence-based and sustainable way.