

Data Backup Software: Building a Protective Layer Against Unexpected Incidents

Data is often noticed only after it has disappeared. An overwritten project folder, an inaccessible hard drive, a locked storage account, or a simple mistake can make hours of work worthless. At that point, the important question is not how many files the business had, but how much data can be recovered within an acceptable period of time.
Data backup software turns file protection from a manual task into a repeatable process. The tool can automatically copy folders, save multiple versions, encrypt copies, send notifications when errors occur, and support recovery of individual files or entire systems. However, installing software does not mean that the data is automatically safe. Effectiveness depends on how data is selected, how the backup schedule is designed, how copies are separated, and whether recoverability is tested.
Backup Is Not the Same as Data Synchronization
One common misconception is to view a file synchronization service as a complete backup system. Synchronization allows the same data to appear on multiple devices, making it convenient to work from a computer, phone, or browser. But if a file is deleted or replaced with an incorrect version, that change may be transmitted to other devices. Without version history or an independent copy, fast synchronization can even eliminate the opportunity for recovery.
Backup is intended to preserve data states at different points in time. Good backup software generally allows users to choose how often copies are created, how long old versions are retained, and what to do when storage capacity decreases. As a result, users can return to a point in time before an error occurred instead of seeing only the latest state.
These two activities can be used together, but they serve different purposes. Synchronization is suitable for everyday access and collaboration. Backup is suitable for recovery after accidental deletion, device damage, software errors, or security incidents.
Start by Classifying the Data
Not every file needs to be backed up with the same level of priority. Photos, personal documents, customer data, databases, source code, and system configurations may have very different values. If an entire drive is placed on a single backup schedule without classification, the process may consume a great deal of storage space and time while still overlooking the data that needs to be recovered most quickly.
Before choosing a tool, it is advisable to make a list of important data groups. For a website, these may include source code, databases, uploaded files, server configurations, and the information needed to redeploy it. For an office workgroup, they may include contracts, spreadsheets, accounting documents, project records, and shared folders. Temporary files, installers that can be downloaded again, or data whose original version already exists elsewhere can be assigned a lower priority.
Classification should also answer three questions: how long can the data be lost for at most, how quickly does it need to be recovered, and who is responsible for carrying this out? A file that is updated continuously may need to be backed up more frequently than a rarely changed archive document. An online operating system may require a rapid recovery process, while a personal photo archive may tolerate a longer recovery time.
Features Worth Considering When Choosing Software
Automatic and Flexible Backup Schedules
Manual backups are easy to forget, especially when users have to focus on their main work. An automatic schedule reduces dependence on memory and creates a stable operating rhythm. The software should allow different schedules to be configured for different data groups; for example, active data could be backed up more frequently than a long-term archive.
In addition to the run time, attention should be paid to how the tool handles situations in which the device is turned off or has no connection. A good schedule does more than record the expected time: it also provides catch-up execution, error reporting, and a way to avoid creating multiple overlapping tasks. Administrators should also know whether the software continues backing up after a user logs out or when the computer enters sleep mode.
Multiple Versions and Selective Recovery
The newest copy is not always the most useful one. If data has been silently corrupted over several days, retaining only one version will not be enough. The ability to save versions by date or time period helps users find the state that existed before the error appeared.
Selective recovery is also very important. In many situations, users only need to retrieve a single file or folder rather than restore the entire device. A clear search interface that displays when the copy was created and allows the original path to be viewed will reduce the risk of restoring the wrong data.
Encryption and Access Control
Backup copies often contain information with a value equivalent to that of the original data. Therefore, protecting copies should be regarded as part of security, not as an optional add-on. Users should find out whether data is encrypted in transit, at rest, or in both states. They should also know who has permission to view, download, delete, or change the backup configuration.
In a multi-user environment, administrative access should not be granted to every account. The backup operations account, data-viewing account, and recovery account can be separated according to need. If the software supports multi-factor authentication, this feature should be enabled for accounts with elevated privileges. Passwords or recovery keys also need to be stored in a secure place, because an encrypted copy that cannot be reopened will not resolve the incident.
Notifications and Activity Logs
Software that remains silent when a task fails can create a false sense of security. Email notifications or a dashboard help the person in charge know whether the latest copy has completed, whether storage is nearly full, and whether there are problems connecting to the storage location.
Activity logs need to provide enough detail to answer basic questions: when did the task start, which data groups did it process, were any files skipped, and where did the error occur? This information supports configuration adjustments before a real incident happens.
Design Multiple Layers Instead of Using Just One Storage Location
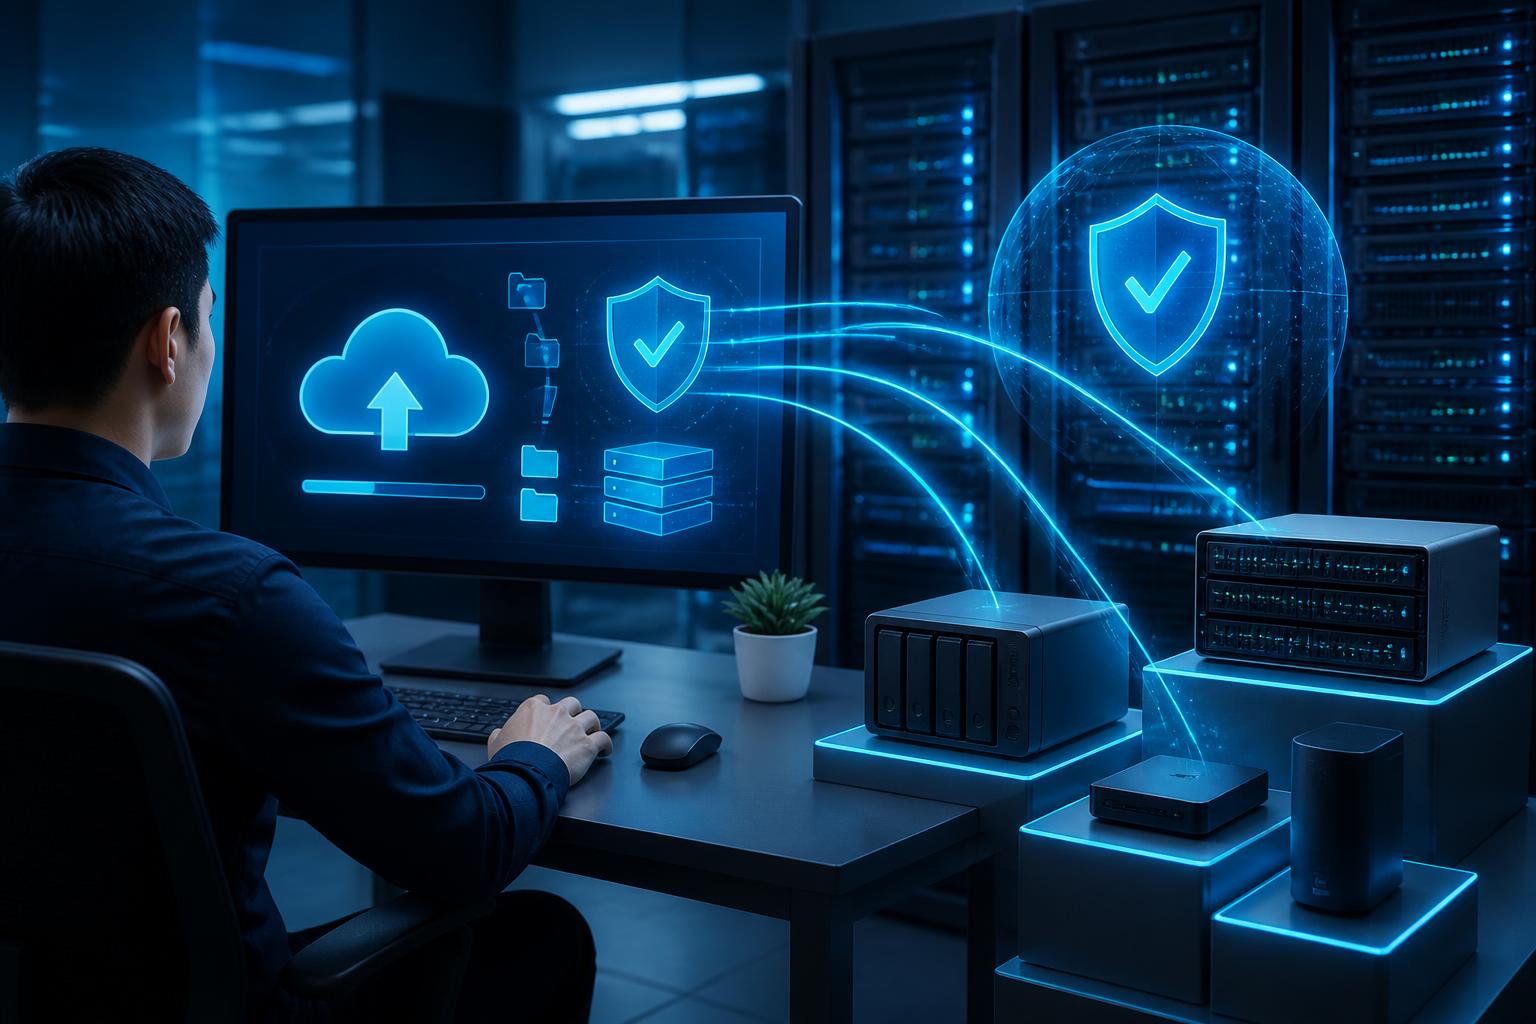
A copy placed next to the original data cannot protect the data against every risk. If the computer and backup drive are damaged, lost, or encrypted in the same incident, neither copy may remain usable. Therefore, the backup process should include copies stored in different locations and environments.
A commonly cited principle is to maintain multiple copies, use multiple types of storage media, and keep at least one copy in a separate location. The specific implementation may vary depending on the scale. Individual users can combine an external storage drive with online storage. Small teams can keep one copy on the work device, one copy on a server or cloud service, and one separately controlled offline copy. The important thing is not to make every copy dependent on a single account, device, or connection.
Offline copies have the advantage of being less affected by changes that occur continuously on a connected system. However, they require discipline when connecting, copying, disconnecting, and storing them. Online copies are more convenient for automation and remote recovery, but attention must be paid to access permissions, retention policies, and version control.
Recovery Testing Is the Decisive Step
Many backup processes stop at checking whether the software has finished running. A completed task does not guarantee that every file can be used. Files may have been skipped because of access permissions, a copy may be missing a related component, or the recovery configuration may no longer be compatible with the current system.
Therefore, recovery should be tested periodically. Testing can begin with a single file and then expand to a folder, a database, or a test environment. After each test, it is advisable to confirm that the file opens, that the data is complete, and that the person performing the recovery knows the necessary steps.
For websites and applications, recovery involves more than copying files back. It may require setting up an environment, loading a database, adjusting configurations, and checking important functions. Documenting the process in concise instructions will help reduce dependence on one person. If the person in charge is absent when an incident occurs, another team member will still have a basis for continuing.
Mistakes That Reduce the Value of Backups
The first mistake is backing up everything without knowing where the data is located. A process without a clear inventory can easily miss important folders or create excessive amounts of redundant data. The next mistake is setting a schedule that is too infrequent compared with the rate at which the data changes. In that case, a copy may exist but still leave a large gap between saves.
Another problem is failing to monitor storage capacity and retention periods. When storage is full, the software may stop tasks or automatically delete old versions according to a policy that the user has not noticed. Automatic configurations need to be reviewed after changes to data, devices, or personnel.
Finally, backup software should not be viewed as a substitute for basic security. System updates, access control, protection of administrative accounts, and user training still need to be carried out in parallel. Backups improve the ability to recover, but they do not prevent every incident from occurring.
Turn Backup into a Process That Is Easy to Maintain
A sustainable process does not necessarily have to be complicated. Start with the most valuable data, choose an appropriate schedule, identify at least two storage locations, and assign responsibility. Then gradually add layers of protection such as encryption, version retention, error notifications, and recovery testing.
The software name, folder list, operating schedule, locations where copies are stored, data retention period, and recovery steps should be documented. This documentation needs to be updated when devices, accounts, or folder structures change. A periodic review can identify gaps that the software dashboard cannot resolve on its own.
The value of backup software does not lie in the number of options, but in its ability to create a copy that can be found, opened, and restored at the right time. When designed as a multilayered process, backup becomes a foundation that helps individuals and businesses reduce disruption, protect the effort they have invested, and take greater control in the face of unpredictable incidents.